
A clear breakdown of what Brainforge fixes, how fast, and what it actually delivers.
For the past three years, the data engineering community has been arguing about table formats. Iceberg vs. Delta Lake vs. Hudi. Which open lakehouse format would win?
That debate is effectively over.
Apache Iceberg has become the default. Delta Lake now exposes tables via Iceberg-compatible APIs through UniForm. Apache Hudi supports Iceberg readers natively. Even Databricks, Delta Lake's creator, ships Iceberg-compatible exports. The format war produced a clear winner, and every major vendor has acknowledged it.
But here's what most articles are missing: the real lock-in risk has shifted to catalogs.
If your team is evaluating a lakehouse strategy right now, or you're mid-migration and feeling confident you've solved the hard problem, this post is worth reading before you declare victory.
What Is a Table Catalog, and Why Does It Matter?
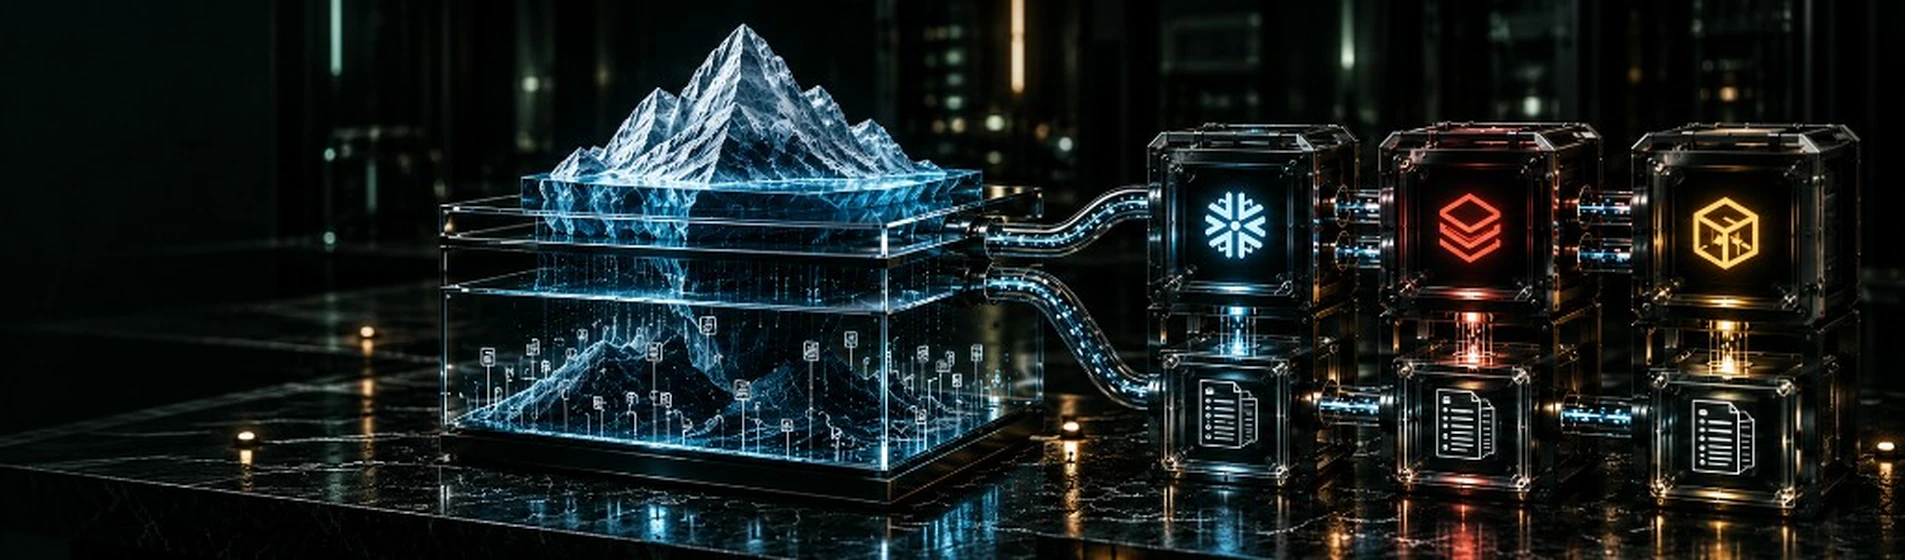
A table format like Iceberg defines how data is stored and versioned on object storage. A catalog is the metadata layer that tells your query engines where that data lives and what it looks like.
Think of it this way: Iceberg is the filing system. The catalog is the index.
Without a catalog, every query engine connecting to your lakehouse has to independently discover table locations, schema definitions, partition layouts, and snapshot histories. That's not scalable. The catalog centralizes this metadata so that Spark, Trino, Snowflake External Tables, DuckDB, and any other engine can find and read the same tables consistently.
The practical implication: whichever catalog you standardize on, you're building deep operational dependencies into it. Your CI/CD pipelines, your dbt project, your access control policies, your cross-account sharing configurations. All of it runs through the catalog. Migrating catalogs later is painful in ways that migrating table formats is not.
The Three Catalogs That Matter Right Now
Snowflake Horizon Catalog / Apache Polaris
Polaris is Snowflake's open-source Iceberg catalog, built on the Apache Iceberg REST catalog spec. It was open-sourced in mid-2024 and is now managed by the Apache Software Foundation as Apache Polaris (Incubating).
The pitch: because Polaris implements the open REST spec, any engine that speaks Iceberg REST, Spark, Flink, Trino, Snowflake itself, can connect to it without vendor lock-in. In theory, you could run Polaris on your own infrastructure and maintain full portability.
In practice, the Snowflake-managed path has changed. Existing Snowflake Open Catalog customers can continue using Open Catalog and create additional accounts, but new customers are being directed to Snowflake Horizon Catalog for Apache Iceberg tables and multi-engine interoperability. Teams that want the open Polaris control plane without Snowflake's managed service can still evaluate Apache Polaris directly, but they need to own the operational overhead themselves.
Best for: Snowflake-primary teams that want to extend their lakehouse beyond Snowflake compute while staying aligned with Snowflake's governed catalog roadmap. Existing Open Catalog accounts can keep using that path; new Snowflake customers should evaluate Horizon Catalog first.
Databricks Unity Catalog
Unity Catalog is Databricks' unified governance layer for data, ML models, and notebooks. It's tightly integrated with the Databricks platform and has become the de facto standard for teams running serious Spark workloads.
Unity Catalog supports Iceberg reads (and writes, with some constraints) and exposes Iceberg REST endpoints for external engines. It is still most powerful when you're running Databricks compute, but the cross-engine governance story is stronger than it used to be: Databricks now supports cross-engine ABAC so external engines can read Unity Catalog tables with ABAC policies, row filters, and column masks enforced outside Databricks, subject to beta-stage requirements and limitations.
The lock-in concern is real and acknowledged even by Databricks customers we talk to. Migrating off Unity Catalog means migrating your access control policies, lineage graphs, feature store integrations, and audit logs, not just your table locations.
Best for: Teams committed to Databricks as their primary compute platform, who value deep ML/data integration and can accept the ecosystem dependency.
AWS Glue Data Catalog
Glue Data Catalog has been the default catalog for AWS-native lakehouse architectures for years. It integrates natively with Athena, EMR, Redshift Spectrum, and AWS Lake Formation for access control.
Glue added Iceberg table support, but it's a different model than Polaris or Unity Catalog. It's a Hive Metastore-compatible catalog that can register Iceberg tables, not a native Iceberg REST catalog. This matters for cross-engine interoperability: engines that expect the Iceberg REST spec may need additional configuration.
Glue is also fundamentally an AWS service; it doesn't run outside AWS, which matters if you're running a multi-cloud workload or want genuine compute portability.
Best for: Teams already deeply invested in the AWS ecosystem (Athena, EMR, S3) who aren't planning significant multi-cloud or cross-platform compute expansion.
The Interoperability Question
The data industry's promise with Iceberg was always "write once, query anywhere." The catalog layer is where that promise gets complicated.
True cross-engine interoperability requires a catalog that:
- Implements the Iceberg REST catalog spec faithfully
- Is accessible from outside a single vendor's compute plane
- Enforces access controls at the catalog level (not just compute level)
Polaris comes closest on paper. In practice, catalog interoperability is still early-stage. You'll find rough edges in external engine credential handling, snapshot expiration coordination, and schema evolution across engines. These are solvable, but require real engineering effort that doesn't show up in product demos.
For most mid-market teams, the honest recommendation is: pick the catalog that aligns with your primary compute platform, invest in Iceberg-native table management practices (schema versioning, partitioning strategy, snapshot retention policies), and defer the multi-catalog interoperability problem until you have a concrete use case that demands it.
What Should Mid-Market Teams Actually Do?
Here's the practical framework we're using with clients right now:
If you're Snowflake-primary
Evaluate Horizon Catalog for workloads that need governed open table access, like MotherDuck, DuckDB, or open-source Spark jobs that shouldn't pay Snowflake compute costs. Existing Snowflake Open Catalog customers can continue using that managed path, but new customers should not plan around creating a first Open Catalog account. If you specifically need the open Apache Polaris control plane, treat self-hosting as a platform-engineering commitment.
If you're Databricks-primary
Unity Catalog is your path. Lean into it fully for governance. The power is in the integration depth, not in multi-vendor flexibility. If cross-cloud compute portability becomes a future requirement, you'll have a well-governed Iceberg data layer to migrate from. That's a better position than undisciplined raw S3.
If you're AWS-native and compute-agnostic
Glue works fine for Athena-centric workloads. If you're running Spark on EMR and considering Flink or other engines, evaluate whether a standalone Iceberg REST catalog (Polaris self-hosted, or Nessie) gives you better engine flexibility than Glue's Hive-compatible model.
If you're greenfield
This is the rare case where we'd recommend starting with the catalog question before the compute question. Polaris's open REST spec gives you the most optionality. Pair it with a compute-agnostic query layer (DuckDB for interactive, Spark for batch scale) and you can defer the Snowflake vs. Databricks decision until your usage patterns are clearer.
The Brainforge Take
The Iceberg format war ending is good news for the industry. Standardizing on a common table format reduces the lowest-level lock-in and makes data more portable at rest.
But teams celebrating too early are missing the next layer of risk. Catalogs are where governance lives, where access control lives, and where the practical work of operating a multi-engine lakehouse gets done. Choosing a catalog is a multi-year commitment in a way that choosing a table format no longer is.
Our recommendation: make the catalog decision deliberately, with eyes open to the trade-offs. Don't let it default to "whichever catalog comes bundled with our primary compute platform" without evaluating whether that choice serves your data strategy long-term.
As a Snowflake partner, we're working closely with Polaris-based architectures for clients who want open lakehouse flexibility without giving up Snowflake's governance and query performance. If you're navigating this decision, we're happy to share what we're seeing in practice. Reach out to start a conversation.
